Projects
Each project has its own page with the method, the results, and interactive figures.
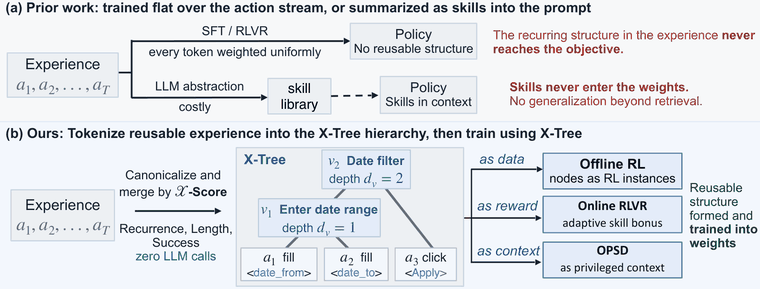
Agents are trained on flat action streams and ignore the sub-procedures that recur across tasks. X-Tree mines this reusable hierarchy from existing trajectories with zero LLM calls, and trains it into the weights as data, as reward, and as context.
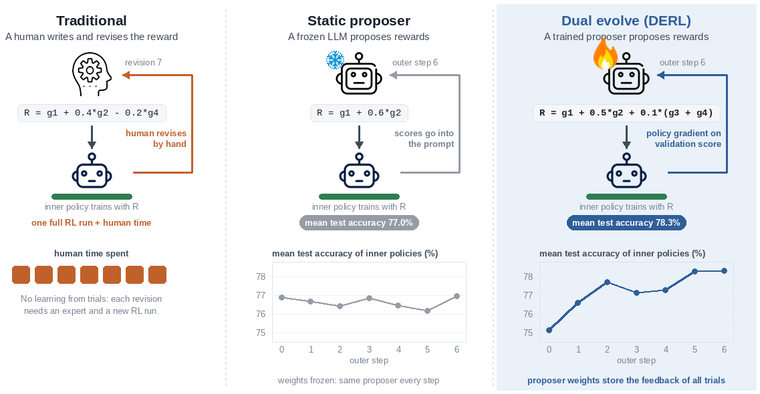
Automated reward design usually searches with a proposer that never learns. DERL tunes the proposer itself with its trials and their scores: a small model composes rewards from task primitives and learns by policy gradient from the validation performance of the policies its rewards train.
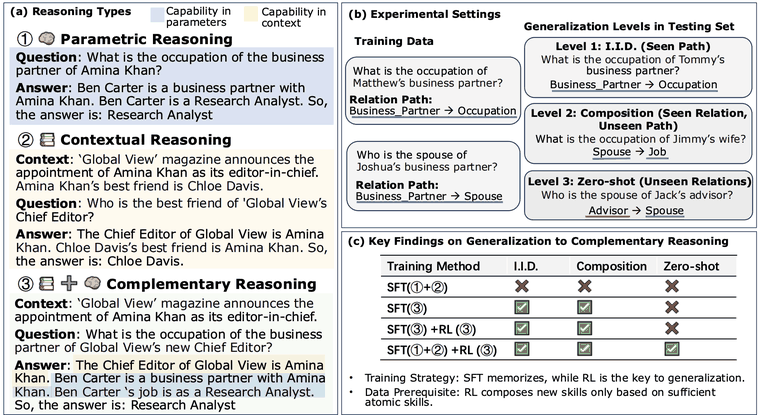
Does RL synthesize new reasoning skills or only amplify existing ones? On a controlled synthetic benchmark, SFT memorizes the composite task, while RL generalizes to unseen compositions once the base model has the atomic skills.