From Atomic to Composite: Reinforcement Learning
Enables Generalization in Complementary Reasoning
1University of Waterloo · 2Duke University · 3National University of Singapore · 4Princeton University · 5Peking University · 6University of California, Santa Barbara
Contact: sitao.cheng@uwaterloo.ca · liangmingpan@pku.edu.cn · victor.zhong@uwaterloo.ca
TL;DR We build a contamination-free benchmark of synthetic biographies and find two things. (1) SFT on composite questions memorizes the seen reasoning paths and fails on unseen relations. (2) RL generalizes to unseen compositions, but only after the model learns the atomic skills: recalling facts from its weights and reading facts from the context.
Read the abstract
Does Reinforcement Learning (RL) merely amplify existing skills, or does it synthesize new ones? We study this question through Complementary Reasoning: the capability of integrating knowledge stored in model weights with novel information provided in context, a prerequisite for continual learning and retrieval-augmented generation. To avoid pre-training contamination, we construct a controlled semantic-synthetic dataset of biographies and decompose the capability into two atomic skills: Parametric Reasoning (retrieving facts encoded in model weights) and Contextual Reasoning (processing novel in-context information). We present two findings. First, models supervised directly on the composite task reach high accuracy on seen facts and reasoning paths (90%) but collapse on paths with unseen relations (18%), indicating that Supervised Fine-Tuning (SFT) relies on memorization rather than skill integration. Second, RL closes this generalization gap and acts as a behavioral synthesizer rather than a mere amplifier, but only under a strict prerequisite: it composes new strategies only when the base model has first acquired the independent atomic skills via SFT. These results suggest that decoupled atomic training followed by RL offers a scalable path to complex and novel reasoning.
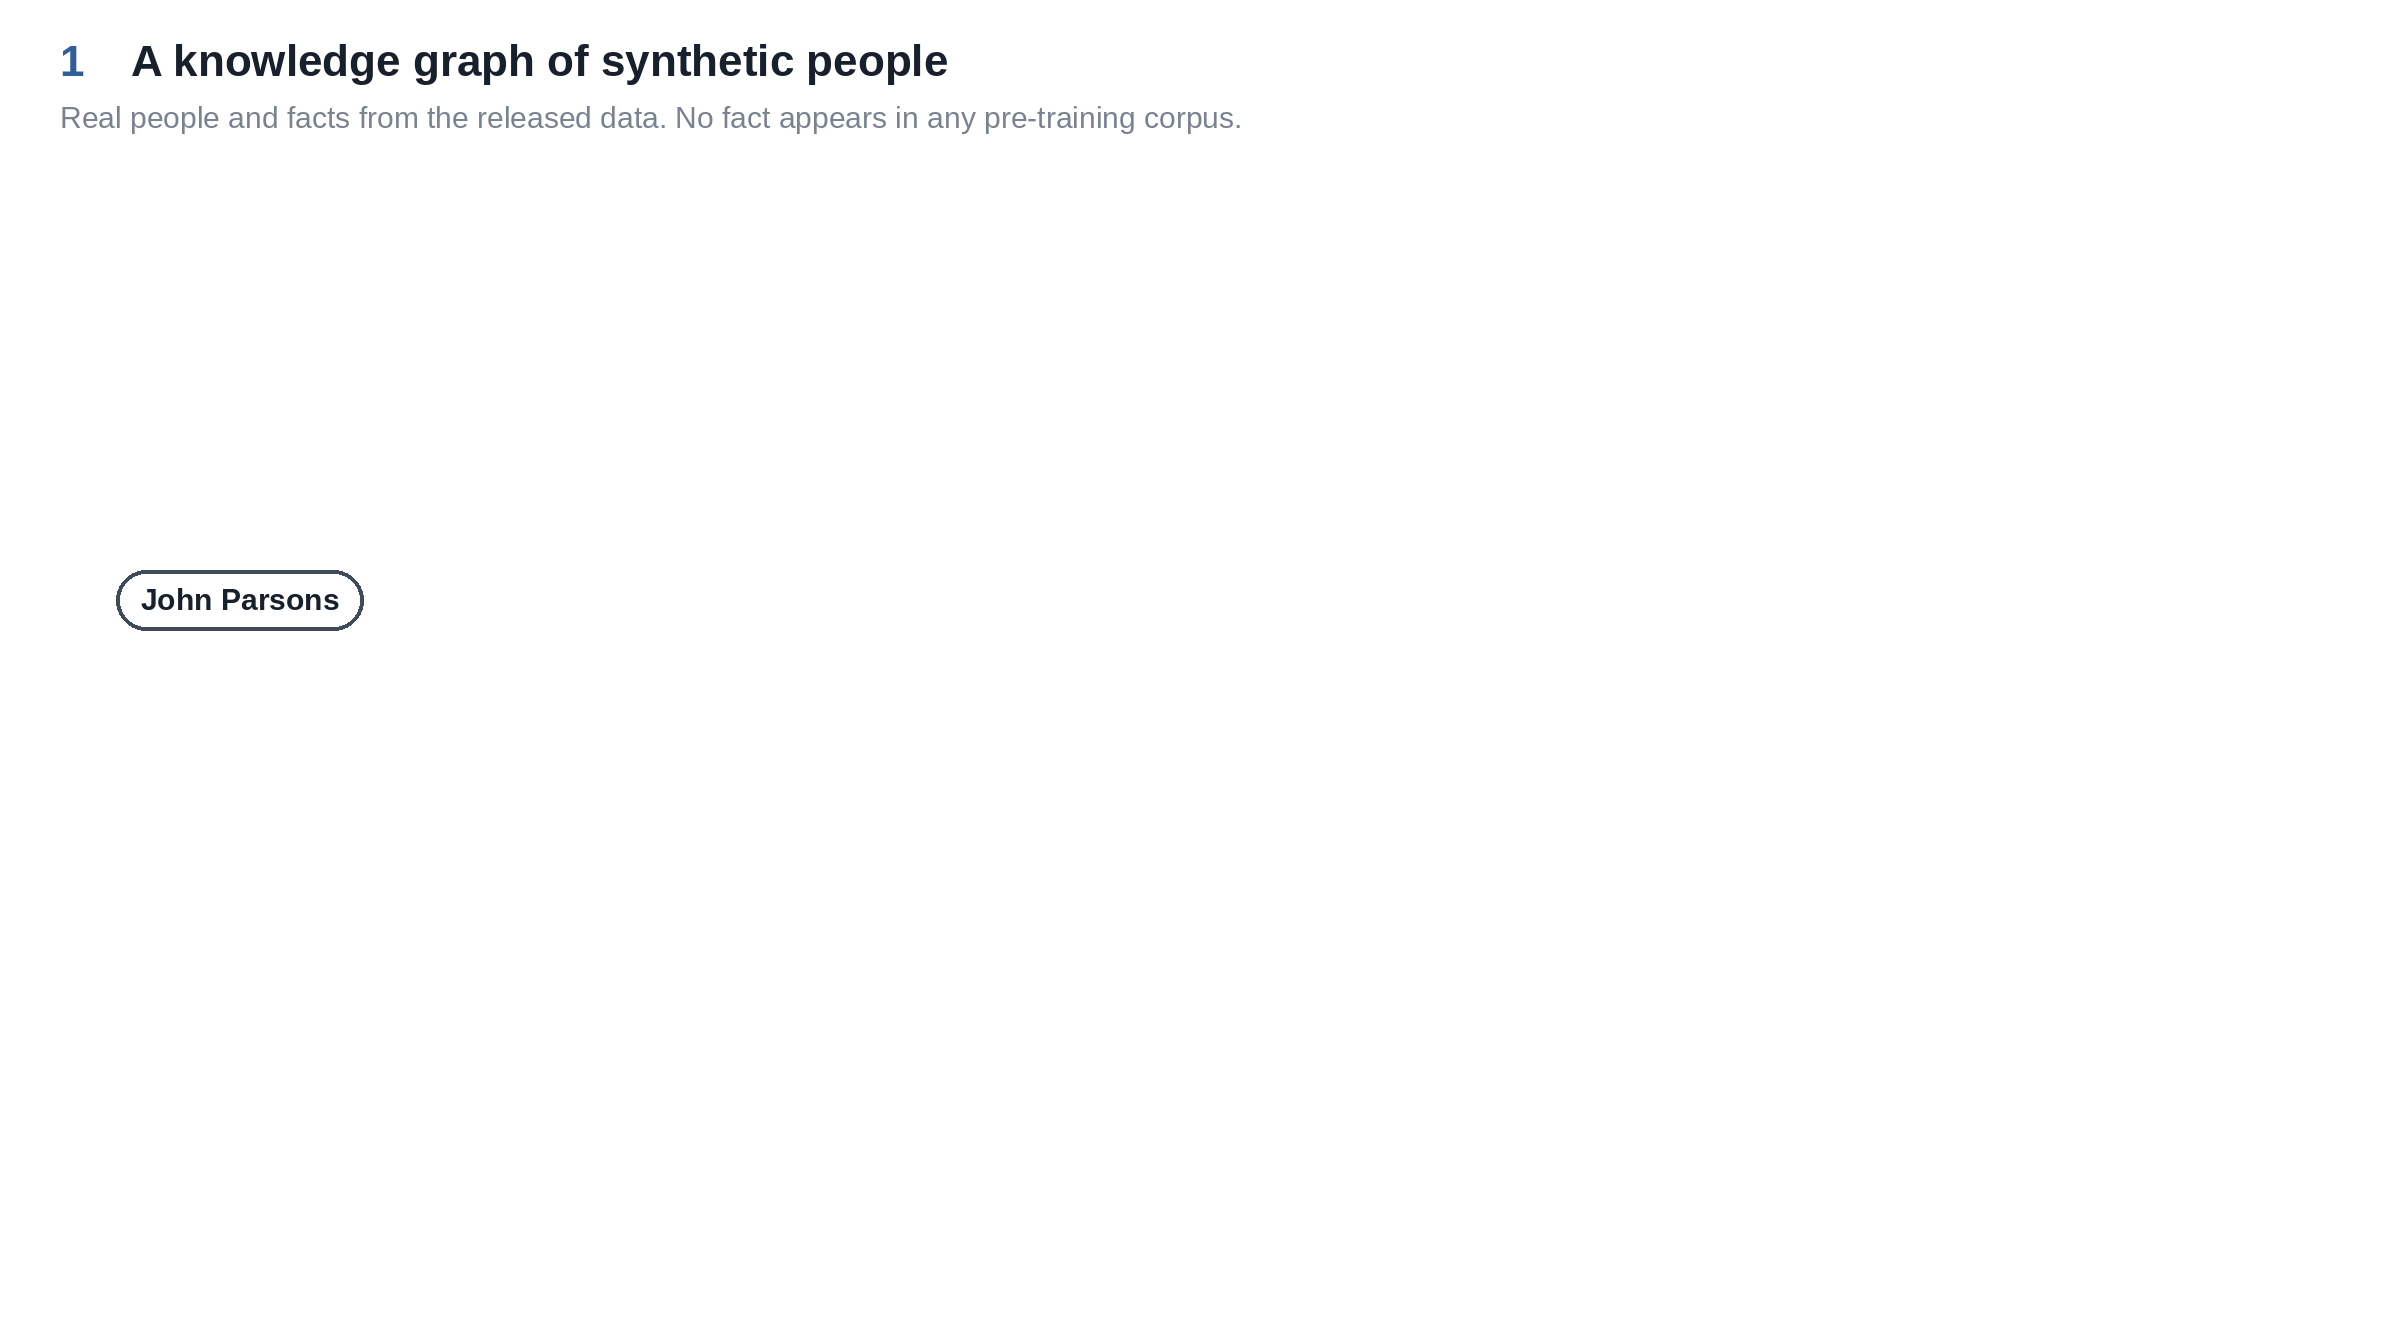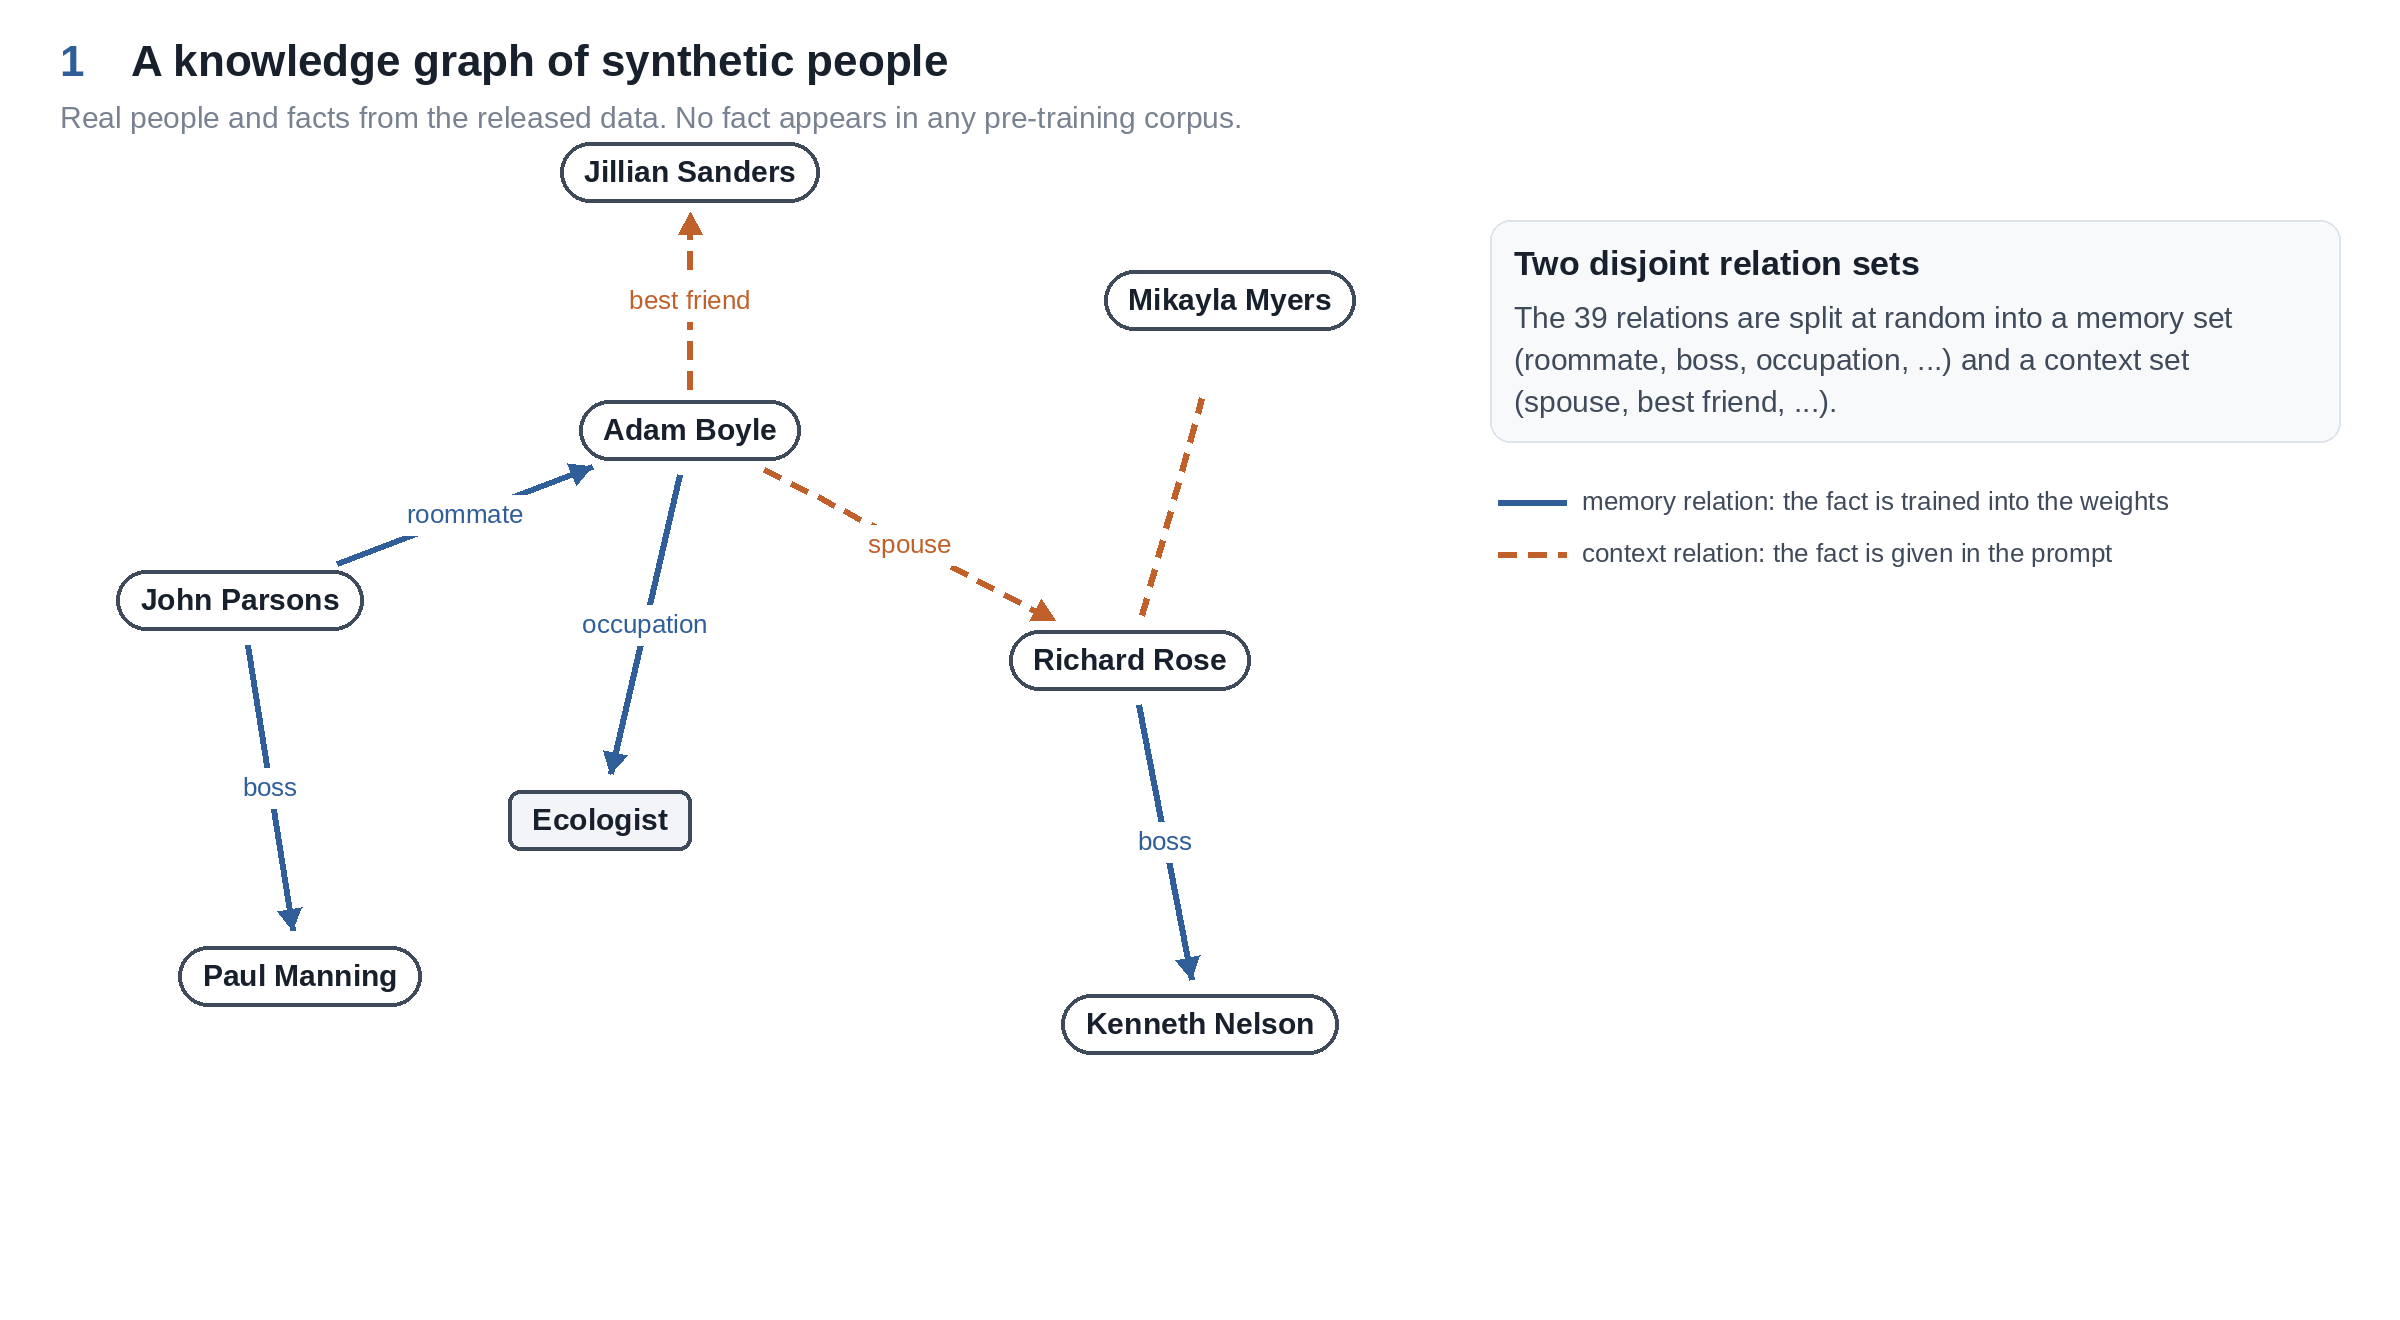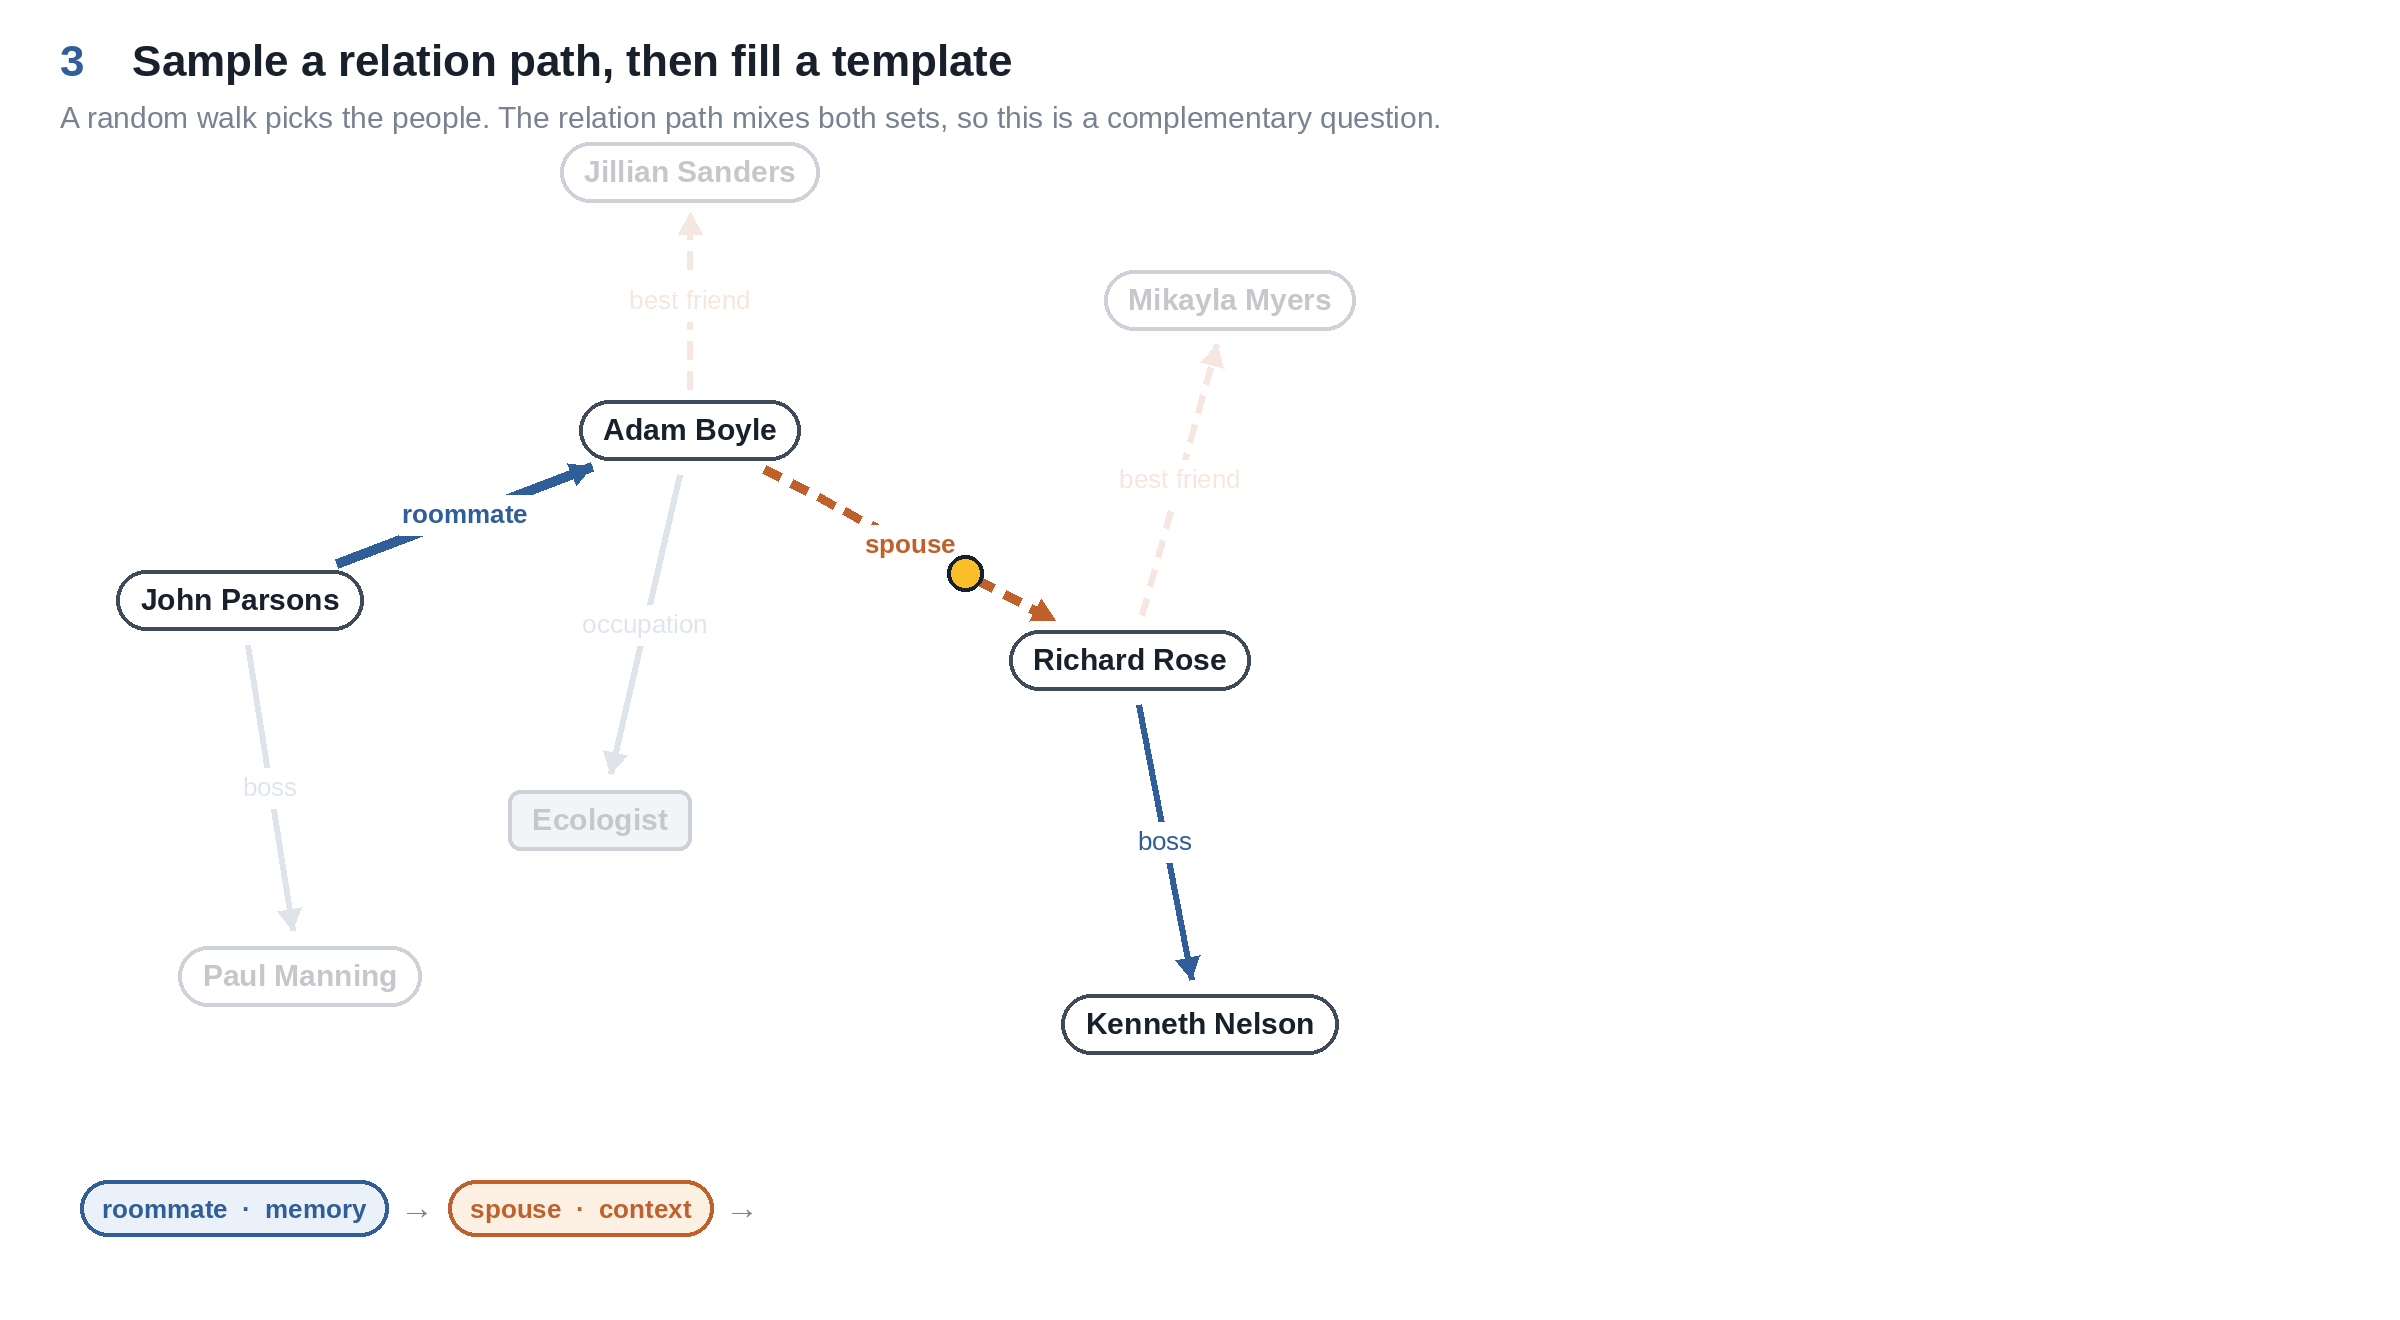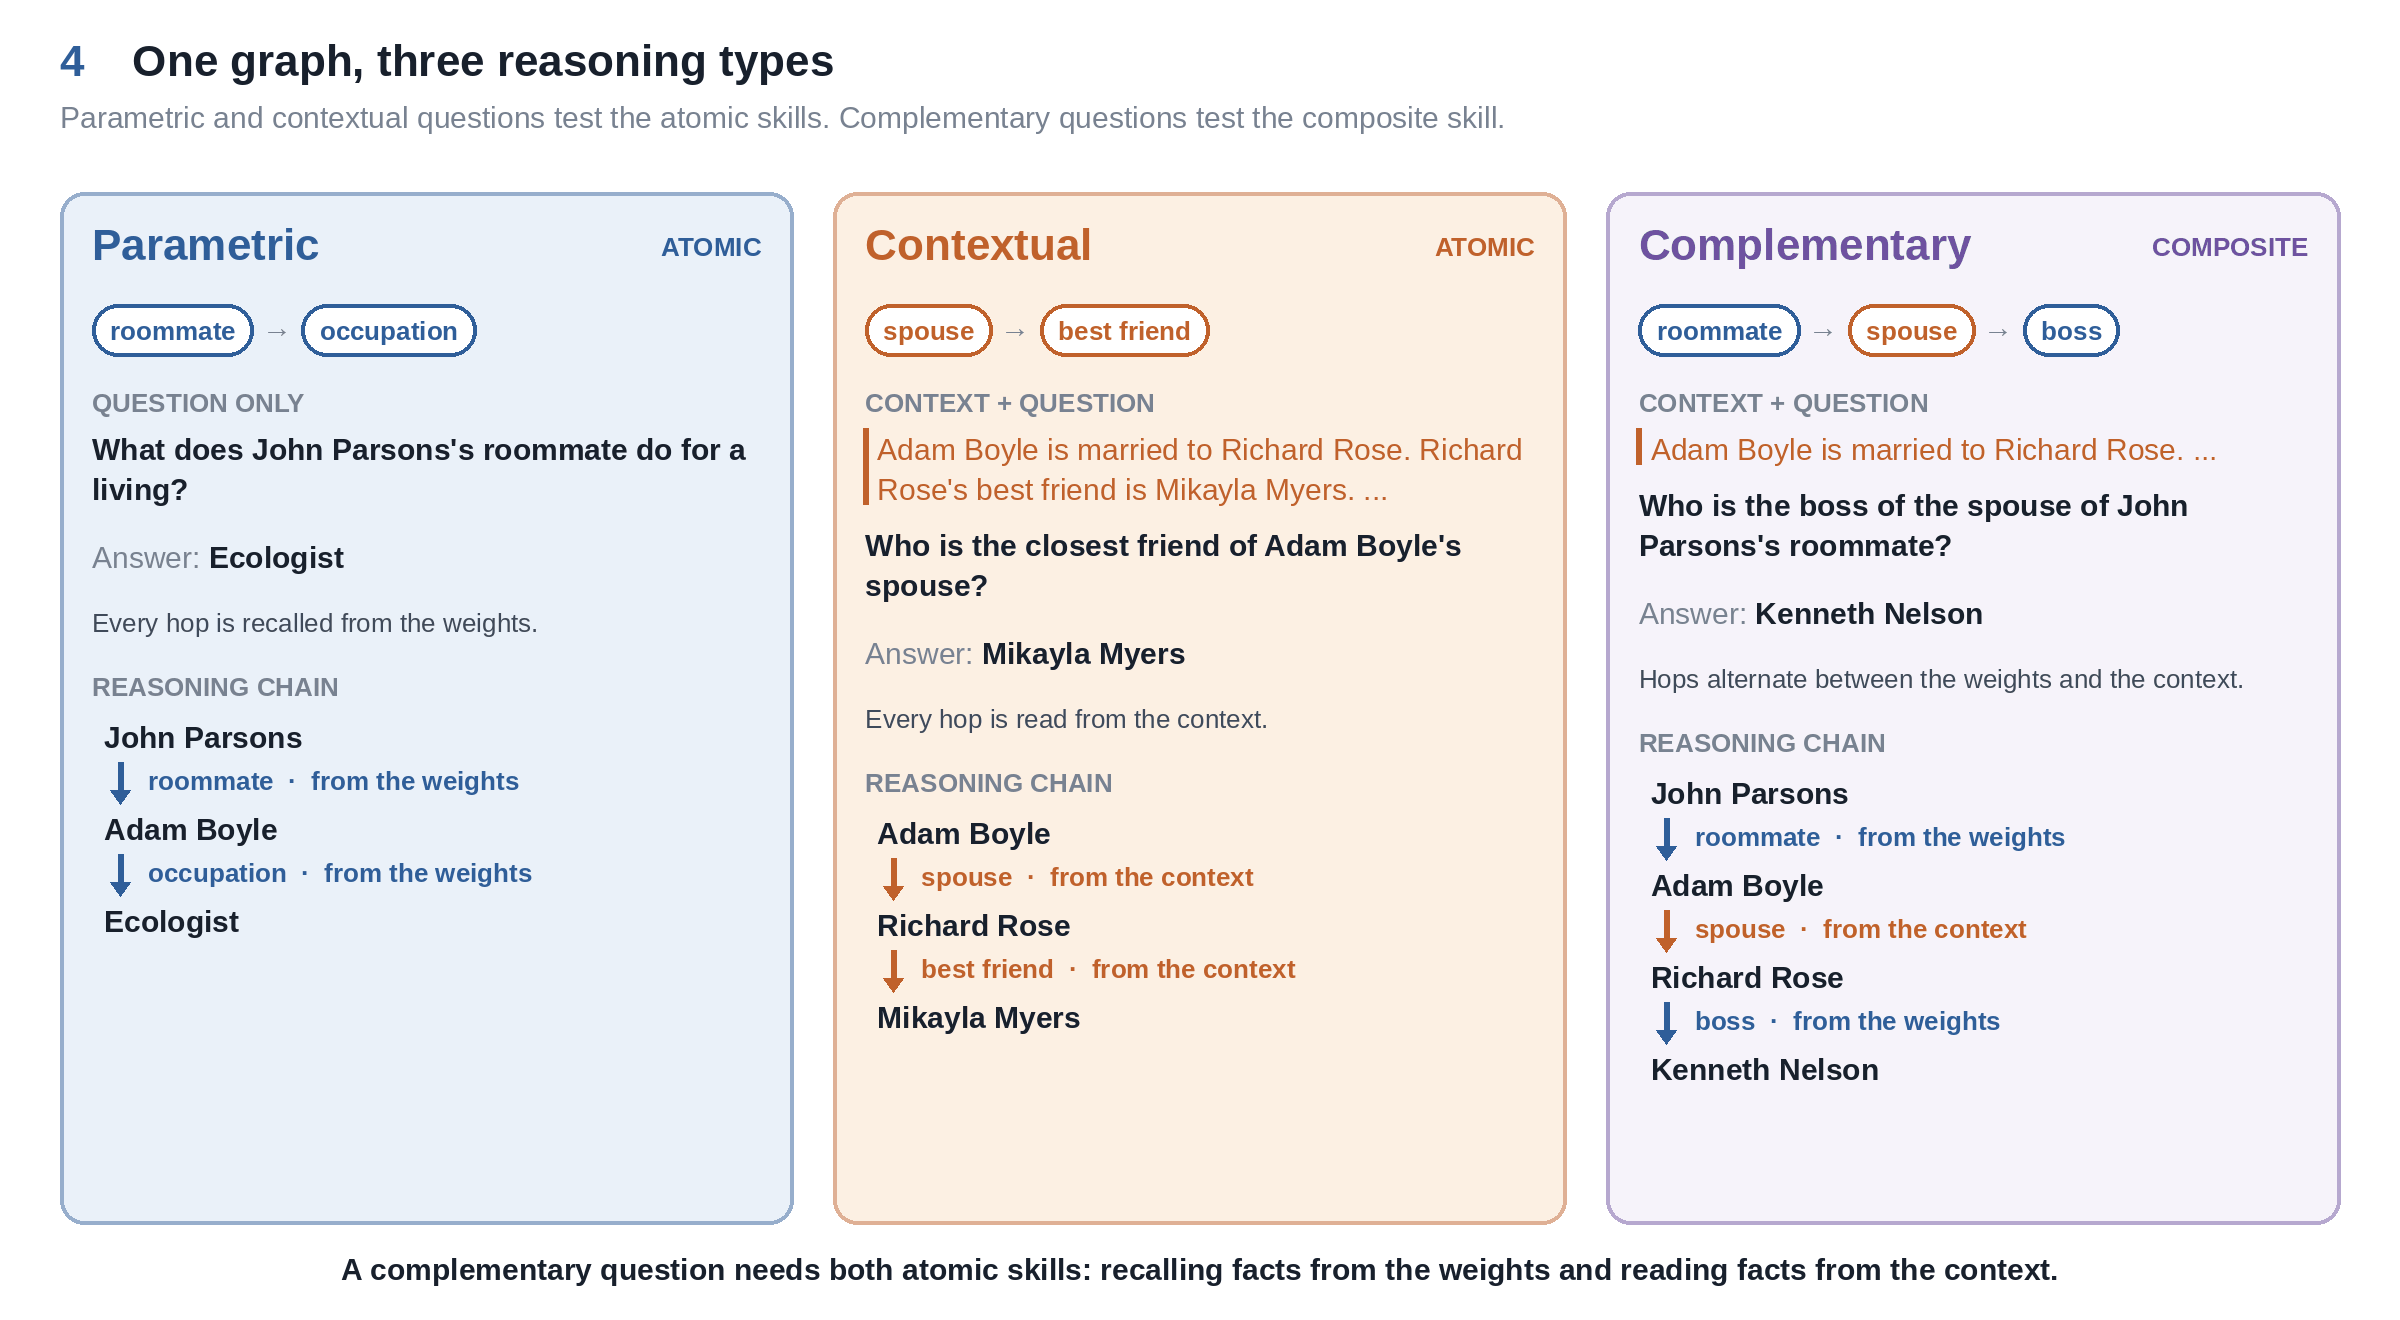
Atomic data tests one skill at a time: parametric questions recall facts from the weights, and contextual questions read facts from the context.
Composite data tests both at once: each complementary question chains facts from the weights and facts from the context.
One knowledge graph, three reasoning types
Every fact comes from a synthetic knowledge graph, so no fact appears in pre-training data. Where a fact lives decides which skill a question needs: memory facts are trained into the weights, and context facts are given in the prompt.
Seen path, new people
The relation path appears in training, asked about different people. SFT is enough here, because the model only recalls an observed structure.
Seen relations, new order
Every relation appears in training, but never in this combination. The model must assemble known relations into a new path.
A relation never trained
The path contains a relation that no training question uses. Memorized patterns cannot help, so this level tests real composition.
RL composes skills, if the atomic skills come first
SFT memorizes rather than generalizes
SFT directly on 181k complementary questions reaches 90.3% on seen paths but only 18.4% when a relation is new. SFT on the atomic skills alone does not compose them either. Learning each skill does not teach the model to combine them.
| SFT data | IID | Comp. | Zero-shot |
|---|---|---|---|
| Memory + context (atomic) | 35.18 | 28.20 | 24.07 |
| Complementary (composite) | 90.30 | 76.25 | 18.41 |
Atomic-first wins on unseen relations at every data split
We split the composite data into an SFT share and an RL share. Composite-first runs SFT on the SFT share, and atomic-first runs SFT on the atomic data instead. Both recipes then run the same RL on the RL share. At every split, RL adds 18 to 48 points to atomic-first and at most 12 points to composite-first.
IID
Composition
Zero-shot
Show the data
| Split (% SFT / % RL) | Recipe | IID: SFT → RL (gain) | Composition | Zero-shot |
|---|---|---|---|---|
| 10 / 90 | Atomic-first | 35.18 → 83.14 (+47.96) | 28.20 → 65.30 (+37.10) | 24.07 → 48.58 (+24.51) |
| Composite-first | 31.43 → 29.93 (−1.50) | 27.14 → 28.13 (+0.99) | 17.32 → 17.76 (+0.44) | |
| 30 / 70 | Atomic-first | 35.18 → 81.08 (+45.90) | 28.20 → 64.24 (+36.04) | 24.07 → 47.39 (+23.32) |
| Composite-first | 51.15 → 62.81 (+11.66) | 43.25 → 50.81 (+7.56) | 25.93 → 31.15 (+5.22) | |
| 50 / 50 | Atomic-first | 35.18 → 80.61 (+45.43) | 28.20 → 63.39 (+35.19) | 24.07 → 45.97 (+21.90) |
| Composite-first | 72.83 → 78.55 (+5.72) | 57.74 → 63.82 (+6.08) | 27.78 → 28.76 (+0.98) | |
| 70 / 30 | Atomic-first | 35.18 → 79.53 (+44.35) | 28.20 → 62.33 (+34.13) | 24.07 → 43.57 (+19.50) |
| Composite-first | 82.86 → 87.03 (+4.17) | 73.43 → 76.18 (+2.75) | 30.61 → 29.63 (−0.98) | |
| 90 / 10 | Atomic-first | 35.18 → 71.29 (+36.11) | 28.20 → 60.49 (+32.29) | 24.07 → 42.59 (+18.52) |
| Composite-first | 88.90 → 90.35 (+1.45) | 78.37 → 80.35 (+1.98) | 26.25 → 29.85 (+3.60) |
RL needs both atomic skills
We give the same RL (12.8k complementary questions) to models with different SFT. Models that learned only memory facts or only context reading gain little, and so do models with a small dose of composite SFT. Only the model with both atomic skills gains strongly.
Show the data
| SFT data | Zero-shot before RL | Zero-shot after RL |
|---|---|---|
| SFT on 10% composite | 17.32 | 18.85 |
| SFT on 20% composite | 19.50 | 20.81 |
| SFT on memory only | 0.00 | 5.99 |
| SFT on context only | 20.59 | 20.92 |
| SFT on memory + context | 24.07 | 42.59 |
Further SFT is no substitute for RL
From the same atomic model and the same 12.8k composite questions, further SFT gives the best accuracy on seen paths (75.5% vs. 71.3% for RL). On unseen relations RL leads, with 42.6% against 35.7% for SFT and 34.6% for LoRA.
Show the data
| Training on 12.8k samples | IID | Comp. | Zero-shot |
|---|---|---|---|
| SFT | 75.50 | 58.59 | 35.73 |
| LoRA | 64.26 | 53.99 | 34.64 |
| RL | 71.29 | 60.49 | 42.59 |
A synthesizer on atomic skills, an amplifier without them
If RL only amplified behavior the SFT model already has, sampling the SFT model enough times would find the same answers, and the pass@k curves would meet. They meet only for the composite-first model.
Atomic-first: SFT on memory + context
Composite-first: SFT on 90% of the composite data
Show the data
| k | Atomic-first before RL | after RL | Composite-first before RL | after RL |
|---|---|---|---|---|
| 1 | 24.07 | 47.39 | 26.25 | 29.85 |
| 2 | 29.30 | 51.09 | 33.55 | 35.51 |
| 4 | 31.92 | 55.88 | 36.38 | 39.00 |
| 8 | 34.64 | 56.43 | 40.09 | 41.29 |
| 16 | 36.60 | 58.50 | 42.59 | 43.14 |
| 32 | 38.13 | 58.71 | 46.41 | 45.64 |
| 64 | 41.07 | 60.24 | 46.30 | 47.39 |
| 128 | 40.85 | 61.66 | 48.47 | 49.35 |
| 256 | 42.81 | 62.20 | 50.87 | 50.00 |
| 512 | 44.34 | 62.85 | 51.96 | 51.53 |
RL moves the failure point later
Without atomic-first RL, most errors happen early, when the model reads the context. After atomic-first RL, 70% of the remaining errors are in recalling memory facts, and they happen near the end of the chain. RL fixes the bridging between context and memory.
| Model | Ctx | Mem | Progress |
|---|---|---|---|
| SFT on composite | 90% | 10% | 54.5% |
| Composite-first (SFT, then RL) | 86% | 14% | 45.0% |
| SFT on memory + context | 86% | 14% | 18.5% |
| Atomic-first (SFT, then RL) | 30% | 70% | 71.8% |
BibTeX
@article{cheng2025atomic,
  title   = {From Atomic to Composite: Reinforcement Learning Enables
             Generalization in Complementary Reasoning},
  author  = {Cheng, Sitao and Yin, Xunjian and Zhou, Ruiwen and Li, Yuxuan and
             Wang, Xinyi and Pan, Liangming and Wang, William Yang and
             Zhong, Victor},
  journal = {arXiv preprint arXiv:2512.01970},
  year    = {2025}
}